The layer / Memory and knowledge
Retrieval and cited answers, live
NexusRAG
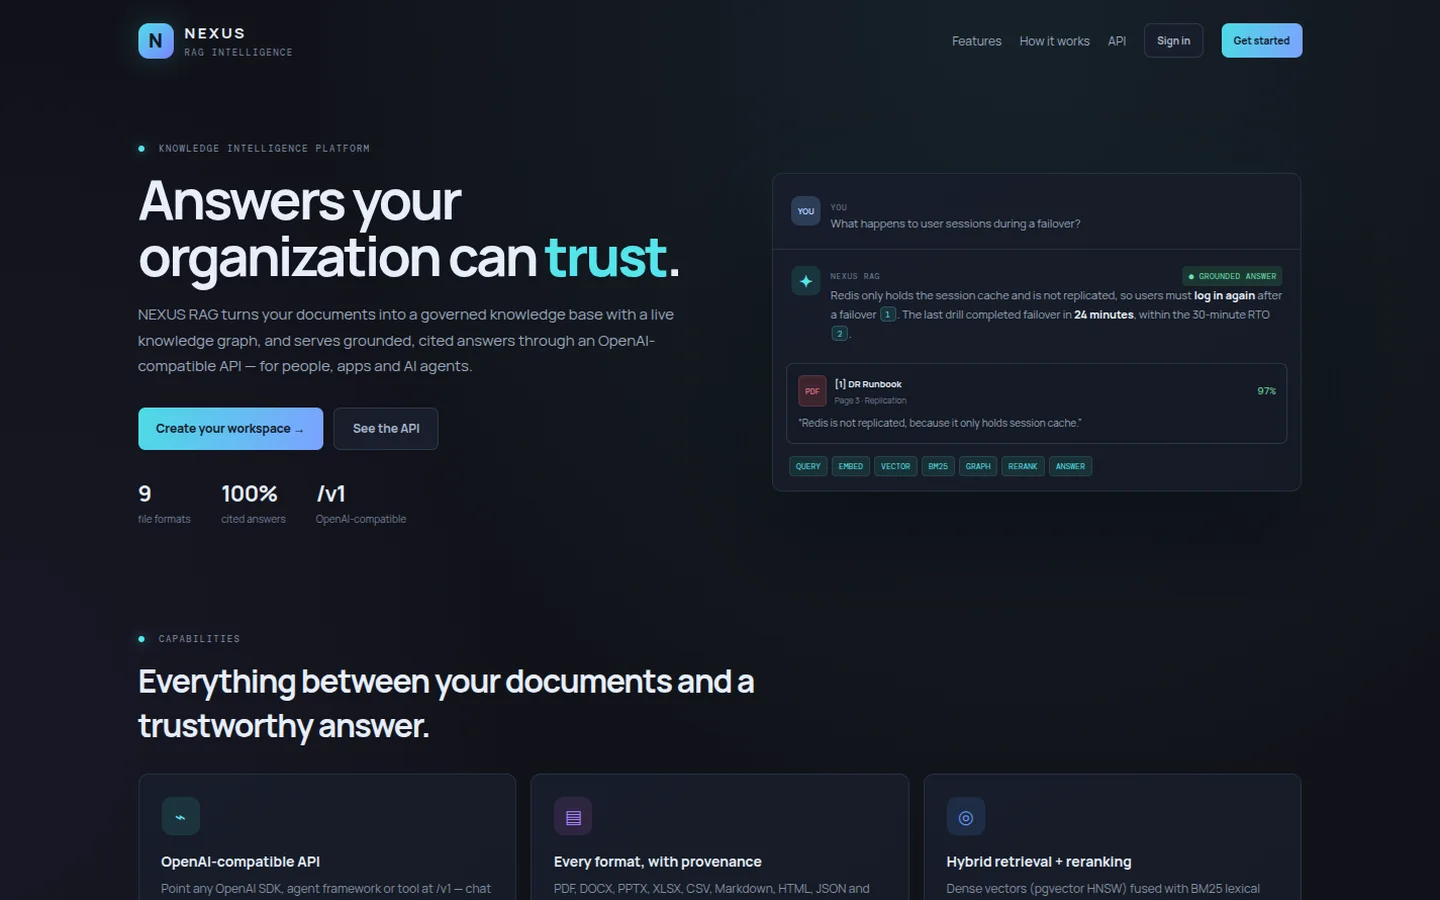
Answers from your documents, with every claim cited.
NexusRAG turns documents into governed knowledge bases and answers questions from them through an OpenAI-compatible API. It combines vector and keyword search, reranks the results, checks every citation against the source text and builds a knowledge graph in which each relationship is backed by a quoted passage.
Why it matters.
A model that answers from company documents is only useful if every answer can be checked. NexusRAG shows exactly which passage supports each statement, and the trace of how it was found.
OpenAI-compatible
Point any OpenAI client or agent framework at /v1; no new SDK needed.
Hybrid retrieval
Vector and full-text search fused, then reranked by a cross-encoder.
Verified citations
Numbered sources with quotes; invalid citations are detected and reported.
Evidence-backed graph
Entities and relationships, each one tied to the passage that proves it.
Where teams use NexusRAG.
Policy and procedure questions
Staff ask in plain language and get the paragraph that answers it.
Grounding agents
Agents call one endpoint and receive cited context instead of guessing.
Document estates
PDF, Word, PowerPoint, Excel, CSV, Markdown, HTML and JSON in one base.
How NexusRAG connects.
NexusRAG relies on the shared foundations of the layer and works alongside the services below. See the full architecture.
Takes part in: a question answered from your own knowledge.
More in memory and knowledge.
Let's build it together.
Whether you want to run your own agents on the layer, discuss one of our products, or need a partner for an AI, Java or enterprise project, we respond within one working day.